Best AI Search Optimization Tools for Perplexity in 2026: Rank Trackers Compared on Evidence
The best AI search optimization tools for Perplexity are the ones that show what Perplexity cited. Free and paid trackers compared on engines, cited sources, history and pricing. Reviewed Nov 8, 2026.
The best AI search optimization tools for Perplexity are the ones that show what Perplexity actually cited. Otterly ($29/mo) is the lowest-priced paid tracker here that includes Perplexity by default, Prime AI Visibility's free Flash plan runs five questions once a month, and Ahrefs' free checker gives a one-off look. None can guarantee a citation, so compare the evidence each one keeps.
| Tool | Engines verified | Perplexity support | Free capability | Entry price | Evidence you can inspect | Limitation |
|---|---|---|---|---|---|---|
| Prime AI Visibility | 5 (ChatGPT, Claude, Perplexity, Gemini, AI Overview-style preview); Flash runs ChatGPT, Claude and Perplexity | Yes, on every plan including free Flash | Free Flash plan: 5 questions across ChatGPT, Claude and Perplexity, one check a month | Starter $69/mo | Prompt, answer, mention vs citation, exact cited source URL, competitor detection, preserved answers, plus a Content Fix draft | Free plan limited to 5 questions and one check a month; confirm Grok or Copilot coverage if either matters; newer platform, shorter history; not a blue-link rank tracker; no crawler or backlink database |
| Otterly.AI | 4 core (ChatGPT, Google AI Overviews, Perplexity, MS Copilot; more as add-ons) | Yes (core engine) | Free trial available | Lite $29/mo | Prompt-level tracking across engines; daily tracking; citation source tracking; recommendations listed as a feature | Lite is 15 prompts; some models are paid add-ons; methodology not sufficiently disclosed |
| Peec AI | Default models: ChatGPT, AI Mode, AI Overviews, Copilot, Gemini; you choose 3 on Starter, Pro and Advanced | As an added model; not in the default list on Starter, Pro or Advanced | Not described on the pricing page | Starter $95/mo (50 prompts) | Prompt-level tracking with citation share and source analytics; Looker Studio integration on Advanced | Higher entry price; Perplexity is an add-on; methodology not sufficiently disclosed |
| SE Ranking | AI Search Toolkit page lists AI Overviews, ChatGPT, AI Mode, Perplexity and Gemini; the free check lists four of them | In the paid toolkit; not in the free check's engine list | Free no-signup check, 5 attempts a day; 14-day trial | AI visibility tracking from $71/mo (75 prompts) | AI visibility check and tracker; part of broader SE Ranking SEO toolkit | Free check excludes Perplexity; methodology not sufficiently disclosed |
| Semrush AI Toolkit | Free checker: ChatGPT, Gemini, Google AI Mode and AI Overviews | Not named on the free checker; confirm for the paid toolkit | Free checker, three checks a day, no account | Confirm the current price and plan scope before upgrading | Sits on Semrush's traditional SEO datasets | Perplexity not named on the free checker; methodology not sufficiently disclosed |
| Ahrefs Brand Radar | Free checker: ChatGPT, Gemini, Perplexity, Copilot and Google AI Overviews | Yes, in the free checker | Free AI Visibility Checker, no signup; a limited preview that uses Ahrefs' prompts | Brand Radar Custom Prompts from $50/mo; AI Visibility Index from $199/mo | Brand Radar within the Ahrefs toolset | Bundled into Ahrefs; methodology not sufficiently disclosed |
| Profound | Enterprise AI-visibility platform | Not publicly disclosed | Not publicly disclosed | Not publicly disclosed (third-party reported Starter ~$99/mo, Growth ~$399/mo yearly) | Methodology not sufficiently disclosed | No public self-serve pricing on its own site; enterprise-oriented |
| Scrunch AI | Not publicly disclosed | Not publicly disclosed | Not publicly disclosed | Not publicly disclosed (third-party reported ~$250/mo Core + custom) | Methodology not sufficiently disclosed | Pricing and method disclosed only via third parties |
| Orchly | Homepage describes an AI visibility and optimization platform with a free trial | Confirm whether the plan includes Perplexity before you choose it | Free trial on the homepage; check the scope of any free Perplexity option | Confirm the current price and plan scope before upgrading | Check for prompt-level answers, citations and exact cited URLs | Confirm Perplexity access and retained evidence before subscribing; methodology not sufficiently disclosed |
Prime, Otterly, Peec, SE Ranking, Semrush, Ahrefs and Orchly rows were checked on vendor pages on November 8, 2026; Profound and Scrunch AI rows date from August 11, 2026. "Not publicly disclosed" means the vendor does not publish it. Third-party reported figures are attributed as such and are not vendor-confirmed.
Who this list is for and how it was compared
This list is for marketers and site owners who want to know whether Perplexity names or cites their brand and which page earned the link. Perplexity citations deserve their own evidence column, so the table separates whether a tool covers Perplexity from what it lets you inspect. Every tool is judged on the same nine criteria: engine coverage, mention versus citation, exact cited source, history, competitor comparison, question tracking, reporting and export, pricing transparency, and whether it helps you move from a finding to a fix. The criteria come from each vendor's public pages; no hands-on test was run and nothing here measures accuracy. For a checklist on engines, cadence, prompt ownership, metric definitions, export and pricing, Prime's guide to choosing an AI visibility tool covers those six axes and recommends a trial with ten of your own buyer questions.
Why most Perplexity tracker comparisons are useless
A Perplexity rank tracker is only as trustworthy as the evidence behind its score. That is the whole thesis of this guide. I have spent two decades in SEO, and the reflex most of us carry over — "give me the number, tell me if it went up" — is exactly the reflex that gets you burned in answer engines. A number with no inspectable evidence behind it is a claim dressed up as a measurement.
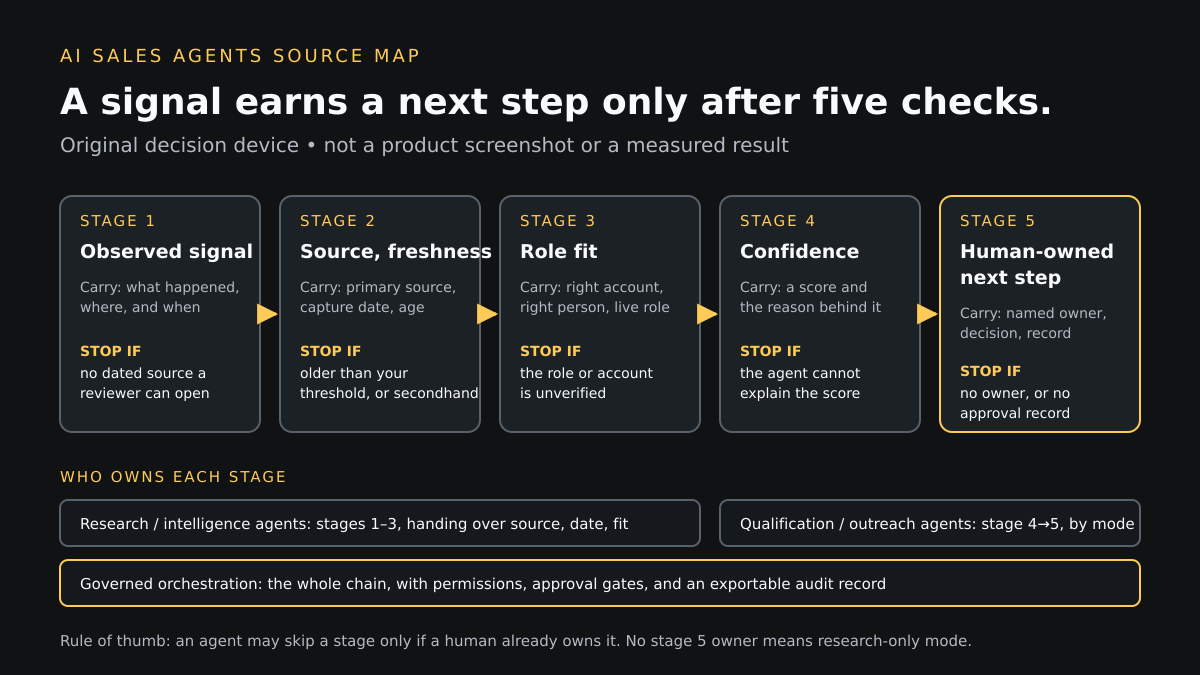
Here is the chain a buyer must be able to inspect before trusting any Perplexity tracker: the exact question asked → the answer returned → whether your brand was mentioned → whether it was cited → the exact URL cited → which competitors appeared → the test conditions → and whether the observation repeats. If a tool cannot show you that chain, it is not measuring your Perplexity presence. It is guessing, and asking you to trust the guess.
This is not the only way to evaluate these tools — it is what I have found effective after watching too many teams buy a dashboard and inherit a number they could not defend.
The PYRA Perplexity Tracker Evidence Test
We score every tool in this guide against a 16-point framework we call the Perplexity Tracker Evidence Test. Each point maps to something a buyer should be able to inspect, not take on faith. The lens is deliberately unforgiving: it does not reward a prettier dashboard, it rewards a tool that can show its work. Below is each point and why it matters.
Notice how few of these points are about the score itself. Twelve of the sixteen are about evidence and repeatability. That imbalance is intentional. In answer engines, the score is the least reliable artifact you can hold; the evidence chain behind it is the part you can actually defend to a CFO.
The tools, reviewed against the Evidence Test
Every tool below is judged on the same 16 points, which extend the nine criteria above. Where a vendor does not publish its method, we say "methodology not sufficiently disclosed" rather than infer it. Where pricing is not published, we say "not publicly disclosed." No tool gets a pass, including ours.
Otterly.AI — best cheapest paid entry
What it is: a prompt-level AI visibility tracker across ChatGPT, Google AI Overviews, Perplexity, and Microsoft Copilot, with Claude, Google AI Mode, and Gemini available as paid add-ons. Verified facts: Lite is $29/mo for 15 prompts across 4 engines; Standard is $189/mo for 100 prompts with API and MCP access; Premium is $489/mo for 400 prompts. Daily tracking; a free trial is available. What the Evidence Test reveals: Otterly scores well on Exact Prompt, Test Context, and Repeatability via daily tracking, and its Perplexity coverage is a core engine rather than an add-on. Its published method does not fully expose the mention-vs-citation-vs-exact-URL distinction, so it earns "methodology not sufficiently disclosed" on the deeper citation points. Who it's for: teams that want the lowest-cost real paid entry to prompt tracking. Limitation: the $29 Lite tier caps you at 15 prompts, and several models cost extra.
Peec AI — strongest multi-model share-of-voice value
What it is: a multi-model tracker whose pricing page lists ChatGPT, AI Mode, AI Overviews, Copilot and Gemini as default models and Perplexity among the models you can add. Verified facts: Starter is $95/mo for 50 prompts with a choice of 3 models; Pro is $245/mo for 150 prompts; Advanced is $495/mo for 350 prompts with a Looker Studio integration; Enterprise is custom. The page shows citation share and source analytics as included features. What the Evidence Test reveals: Peec's prompt volume per dollar at the higher tiers is strong, but Perplexity is not part of the default model set, so confirm it is switched on before you rely on it. Its public method does not clearly separate mention, citation, and exact cited URL, so it lands on "methodology not sufficiently disclosed" for those points. Who it's for: teams that want serious prompt volume across several models. Limitation: the entry price is higher and Perplexity is an add-on.
Profound — enterprise platform
What it is: an enterprise AI-visibility platform. Verified facts: Profound does not publish self-serve pricing on its own site. Third-party reporting (Trakkr, 2026) lists Starter around $99/mo and Growth around $399/mo billed yearly — attributed as third-party reported, not vendor-confirmed. What the Evidence Test reveals: with no publicly disclosed methodology, most of the deeper evidence points return "methodology not sufficiently disclosed." Its positioning is enterprise. Who it's for: larger organizations evaluating an enterprise-grade platform. Limitation: no public self-serve pricing and limited public methodology to inspect.
Semrush AI Toolkit & Ahrefs Brand Radar — the SEO-suite plays
What they are: AI-visibility features that ship inside established SEO suites. Semrush runs an AI Visibility Toolkit as its own product line; Ahrefs offers a free AI Visibility Checker page and ships Brand Radar inside its subscriptions. Verified facts: Ahrefs' free checker lists Perplexity among five engines, and Brand Radar's Custom Prompts start at $50/mo with the AI Visibility Index from $199/mo. Semrush's free checker covers ChatGPT, Gemini, AI Mode and AI Overviews and does not name Perplexity; confirm the current price and plan scope before upgrading. Semrush's strength is that it sits on its traditional SEO datasets. What the Evidence Test reveals: the data-foundation advantage is real for blending AI presence with classic SEO, but the AI-specific citation method is not sufficiently disclosed to score the deeper points. Who they're for: teams already living inside Semrush or Ahrefs. Limitation: AI-visibility is a feature within a larger suite, not a Perplexity-first instrument.
Scrunch AI
What it is: an AI-visibility platform. Verified facts: third-party reporting (2026) lists roughly $250/mo for a Core plan plus custom enterprise — attributed as third-party reported. What the Evidence Test reveals: with method disclosed only via third parties, the deeper evidence points return "methodology not sufficiently disclosed." Who it's for: teams already shortlisting it. Limitation: pricing and method are visible only through third-party sources.
SE Ranking & Orchly — free checks to confirm before you rely on them
What they are: two tools that appear in free Perplexity searches. Verified facts: SE Ranking's free AI visibility check allows 5 attempts a day and lists AI Overviews, AI Mode, ChatGPT and Gemini; Perplexity is listed on its AI Search Toolkit page, and AI visibility tracking starts at $71/mo for 75 prompts on its pricing page, with a 14-day trial. Orchly's homepage describes an AI visibility and optimization platform with a free trial; confirm whether a free option includes Perplexity before you choose it. What the Evidence Test reveals: neither fully exposes the deeper citation-and-URL method, so those points read "methodology not sufficiently disclosed." Who they're for: teams that already use SE Ranking, or that want to test Orchly's platform on a trial. Limitation: SE Ranking's free check does not list Perplexity; for Orchly, confirm Perplexity access, plan scope and retained evidence before subscribing.
Prime AI Visibility — best analysis-to-action, best low-cost monitoring + action
What it is: PYRA's own AI Search Visibility Platform, monitoring five engines: ChatGPT, Claude, Perplexity, Gemini and an AI Overview-style preview built on Google-grounded answers. Verified facts: a free Flash plan gives 30 shared monthly credits for up to five buyer questions across ChatGPT, Claude and Perplexity, one completed check per calendar month; Starter is $69/mo (200 credits, up to 25 buyer questions, all five engines); Growth is $179/mo (600 credits, up to 50 questions per check); Agency is $369/mo (1,300 credits, up to 120 questions per check); Enterprise is $1,499/mo (5,200 credits, up to 500 questions per check), as listed on primeaivisibility.com on November 8, 2026. Exports from saved data are free, and credits for failed usage are refunded. Its method is persona-based buyer questions organized into cohorts, with mention-vs- citation detection, exact cited source URLs, competitor detection, preserved answers, and a "Content Fix" workflow that drafts the content addressing the gaps it finds. What the Evidence Test reveals: Prime is the only tool here that publicly commits to the full mention → citation → exact URL → competitor → preserved answer chain and then adds Actionability by drafting the fix. That is why it wins two, and only two, categories: best analysis-to-action workflow, and best low-cost monitoring plus action platform at $69. Who it's for: teams that want to find the gap and act on it in one place.
Prime's verified limitations (published, not hidden)
- The free Flash plan is limited to five buyer questions and one completed check per calendar month; compare like-for-like saved checks at that cadence rather than expecting weekly monitoring.
- The product page names five engines; confirm Grok or Microsoft Copilot coverage if either matters, and check the paid-plan scope for Gemini and the AI Overview-style preview.
- It is a newer platform with shorter historical data than legacy SEO suites.
- It is not a traditional blue-link rank tracker.
- It has no site crawler and no backlink database.
Prime is not ranked #1 overall in this guide, and it should not be. On a one-off free check with no setup, Ahrefs' checker is simpler. On cheapest paid entry, Otterly's $29 Lite beats it. Prime earns its place only where the verified facts support it: turning an inspected gap into a drafted fix.
Best free Perplexity rank tracker
Two free routes were confirmed on the vendors' own pages. Ahrefs' free AI Visibility Checker lists Perplexity among its engines and needs no signup, but it is a limited preview that uses Ahrefs' own prompts. Prime's free Flash plan lets you choose the questions and keeps the saved answers and sources. SE Ranking's free check lists four engines without Perplexity; for Orchly, confirm the current free-option scope before relying on it.
To be explicit, because it is the single most common mistake buyers make when they see a "free plan" badge: Prime's free Flash plan includes Perplexity, but only for up to five buyer questions and one completed check per calendar month. For a one-off check with no setup, use Ahrefs' checker; for your own questions, use Flash.
Why a ranking number is not the decision
The instinct to reduce all of this to one number is the trap. A Perplexity result is a generated answer that can shift between runs, so a single score is a snapshot, not a fact. The decision lives in the evidence, not the digit.
"In traditional SEO, a position tells you something immediately — you're #3, you know roughly what that means. In answer engines, a ranking number tells you almost nothing on its own. You have to see the question, the answer, the citation, and whether it happens again. The number is where the conversation starts, not where it ends."
I have been doing SEO for 20 years and AI Search before they had a name to it, and the mistake I see most often is treating an answer-engine score with the same trust we gave a Google position. They are not the same instrument.
Mention is not citation is not a cited URL
The clearest way to understand why evidence matters more than a score is an anonymized first-party observation. In an enterprise infrastructure example, across 66 Perplexity runs of 9 buyer questions, exactly one citation was observed. It appeared as a Perplexity source link, and the exact cited article could be identified.
PYRA first-party observation (anonymized), 2026.
Sit with those numbers. Sixty-six runs, nine questions, one citation. If a tracker had simply reported a "visibility score" for that brand, it would have hidden the only fact that mattered: the brand was almost never cited, and when it was, we could pinpoint the exact article that earned it. That is the whole lesson — a mention is not a citation, and a citation is not a specific cited source URL. Three different things, three different levels of evidence, and only the deepest one tells you which page to defend or improve. For the mechanics of tracing that chain, see our guide to Perplexity citation tracking.
The PYRA Same-Prompt Benchmark (Methodology v1.0)
To compare trackers on evidence rather than marketing, we publish the benchmark method itself as a reproducible design. The proposed design uses the same 25 buyer questions in a controlled window, with evidence preserved for every run.
The 25 questions are built from six buyer-question archetypes, so the test reflects how real buyers actually ask, not just head terms:
- Category-definition questions — "what is the best X for Y."
- Comparison questions — "X vs Y for a specific use case."
- Recommendation questions — "which X should a [persona] choose."
- Problem-first questions — "how do I solve [problem]," where the brand may or may not surface.
- Trust / evidence questions — "is X reliable / accurate / safe."
- Price / plan questions — "how much does X cost / what does the free plan include."
Each question is run 2–3 times inside a single controlled window so we can observe drift. For every run we preserve: the raw result, a screenshot, the date, the tool used, the exact prompt, the returned answer, whether a citation occurred, the cited URL if any, any misses, and any errors. That preserved evidence per run is the point — it is what makes a result auditable instead of anecdotal.
What should a Perplexity tracker actually prove?
The following is a conversation between Bob Generale and Alex Mannine, PYRA's Chief AI Officer, about what a Perplexity tracker has to earn before it is worth paying for.
Bob:
When a team asks you how to use one of these dashboards, what's the first thing you tell them?
Alex:
"Look at these as a diagnostic, not a scorecard."
Bob:
A diagnostic of what, though? What do you actually want to see behind a score?
Alex:
The evidence. I want the exact question, the answer that came back, whether we were mentioned, whether we were cited, and the specific URL if we were. A score without that chain is just a mood ring. The evidence is the product.
Bob:
You get twitchy when someone hands you a single number. Why?
Alex:
Because a single number in an answer engine is fragile. Run the same prompt three times and it can move. So one number, with no runs behind it and no evidence preserved, isn't something I'd bet a content roadmap on. I distrust it on principle until I can see it repeat.
Bob:
Say the tool does its job and finds the problem. Then what — you've got a red cell in a grid?
Alex:
"we're giving them the 'what's broken' AND the 'here's the fix' in one platform."
Frequently asked questions
What is a Perplexity rank tracker?
A Perplexity rank tracker is a tool that runs buyer questions through Perplexity's answer engine and records whether your brand is mentioned, whether it is cited, which exact source URL was cited, which competitors appeared, and under what test conditions. Unlike a traditional keyword rank tracker, it is measuring presence inside a generated answer, not a numbered position on a results page.
Is there a free Perplexity rank tracker?
Yes, in limited form. Ahrefs' free AI Visibility Checker lists Perplexity among its engines and needs no signup, but it uses Ahrefs' own prompts. Prime's free Flash plan includes Perplexity for up to five buyer questions you choose, one completed check per calendar month. SE Ranking's free check lists AI Overviews, AI Mode, ChatGPT and Gemini, not Perplexity, so its Perplexity tracking sits behind a paid plan or trial.
How is a Perplexity rank tracker different from SEO rank tracking?
SEO rank tracking reports a stable numbered position for a URL against a keyword. A Perplexity tracker measures whether a brand appears inside a generated answer that can change between runs. Position is fuzzy, answers vary, and a mention is not the same as a citation. That is why repeatability and preserved evidence matter far more than a single number.
What should a Perplexity rank tracker actually prove?
It should let you inspect the full chain of evidence behind any score: the exact question asked, the answer returned, whether your brand was mentioned, whether it was cited, the exact cited source URL, which competitors appeared, the test conditions, and whether the observation repeats. A score with no inspectable evidence behind it is a claim, not a measurement.
How often should I run a Perplexity rank tracker?
Frequently enough to establish a defensible baseline and catch drift, but consistently — same prompts, same conditions. In enterprise planning, the strongest requirement we have seen is not a bigger score but a consistent methodology that creates a defensible baseline over time. Daily tracking exists in several tools; consistency of method matters more than raw frequency.
Can Perplexity tracker results be trusted?
Only to the degree the evidence is inspectable and the observation repeats. Answers vary between runs, so a single result is a snapshot, not a fact. Trust the tools that preserve the answer, the citation, the exact cited URL, and the test conditions, and that let you repeat the run. Distrust any single number presented without that chain.
Does a mention in Perplexity mean I was cited?
No. Mention, citation, and cited source URL are three different things. Your brand name can appear in an answer without a source link, and a source link can point to a competitor's page. In one anonymized first-party observation across 66 Perplexity runs of 9 buyer questions, exactly one citation was observed — and the exact cited article could be identified. Mention is not citation, and citation is not a specific URL.
See the evidence chain on your own brand
Cold: read the benchmark methodology above and run Ahrefs' free checker or Prime's free Flash plan yourself. Warm: see how Prime inspects mention, citation, and the exact cited URL across five engines. Ready: talk with Sales about running it on your real buyer questions.
Methodology
Facts for Prime, Otterly, Peec, SE Ranking, Semrush, Ahrefs and Orchly come from vendor pages checked on November 8, 2026; the Profound and Scrunch AI rows date from August 11, 2026. Tools are assessed against the 16-point PYRA Perplexity Tracker Evidence Test. The proposed Same-Prompt Benchmark provides a reproducible protocol for comparing tools against the same buyer questions and preserving source-level evidence.